Paul Ford about how web browsers are more than enough for application development:
The web browser is very, very, very powerful software for applications, and the cost of accessing that power is going down seemingly every day.
erik gahner larsen on awesome lists losing their shine: the neglected ones go stale, and the rest fill up with pull requests for vibe-coded tools.
I archived awesome-static-generators last month for similar reasons. new generators were turning up faster than I could review them.
Sophia French on microblogging being the next big art movement:
As mega media players and their algorithms burrow themselves further into our lives, a return to the tactics of the early days of microblogging signals more than just nostalgic yearning. It could be the way forward for how artists share their work, process, and life online – on their own terms.
After a few years under Digital Ocean’s ownership CSS-Tricks has a new owner, Geoff Graham, and is an independent site once again.
Andros Fenollosa on why we want small systems instead of decentralized ones when talking about online communities.
There are no commercial interests and people know each other. It’s like a shoe shop in a small town. The shop can only serve a few customers because there is little space, you know the owner’s name (maybe even his wife’s) and the shelves don’t offer much variety; and yet you know you will be well served and the owner wants you to leave with what is best for you.
Cedric on deadpan photography (square framing, flat light, uniform focus) as a style that doesn’t claim neutrality so much as perform it, machinery left on display. The caveat lands well, the same refusal to editorialise reads very differently when the subject is suffering rather than water towers.
John Clary Davies on a 3 A.M. bear at his kitchen window and a record year for human-bear conflicts in Colorado. There have been over 7,000 incidents by early September. A dry winter and drought pushing bears toward houses and a whole town trading stories about cubs on the bike path.
Fugleramme is a real-time bird detection system that listens for birds and renders them as hand-cut 1800s-style illustrations on an e-ink display powered by a Raspberry Pi.
A manifesto making the case that owning your own website instead of feeding a platform is basically punk.
Sami Smith built Misen, a launchpad with a skeuomorphic design of a room. It’s kind of incredible what people are building with the help of LLMs.
Rick Vega made this helpful site to build your own zine.
Love this essay by Conor Dougherty about 40- and 50-somethings who skate a Costco car park before work. Curbs as an excuse to keep showing up for each other.
John Herrick unravel the mysteries of elevators.
An intersting guid for archivist wanting to create disk images of floppy disks with the intention of preserving them for the long-term.
Julia Evans talks about her learnings from using SQLite in production.
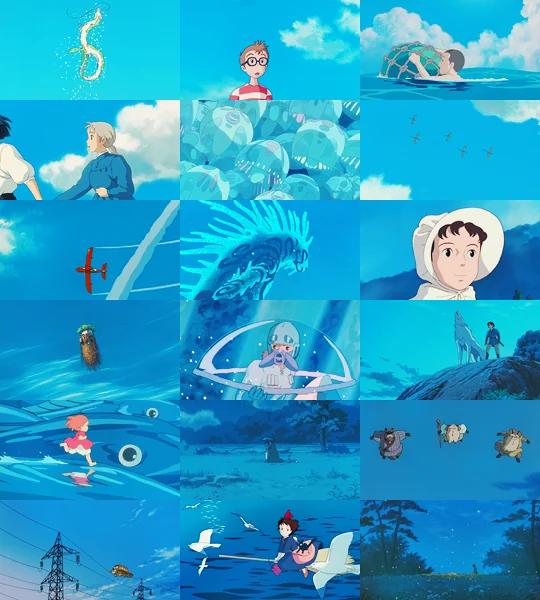
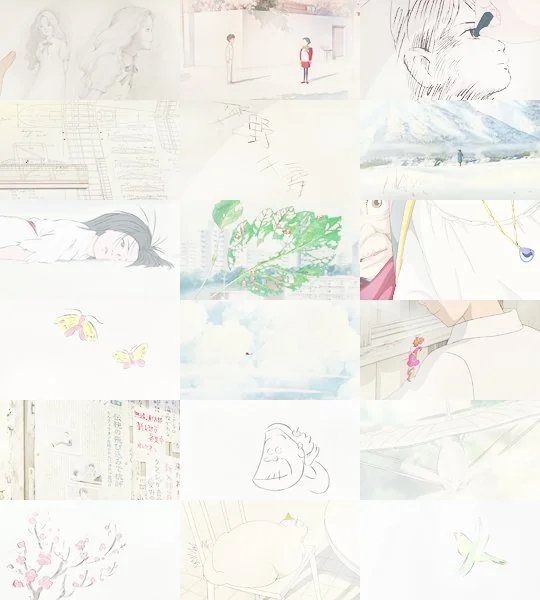
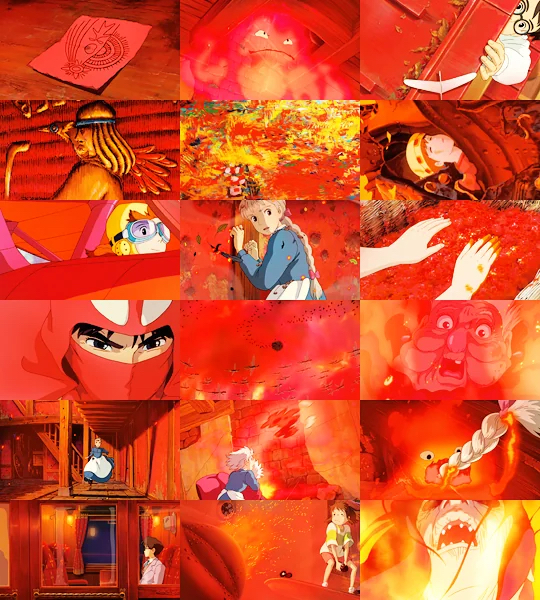
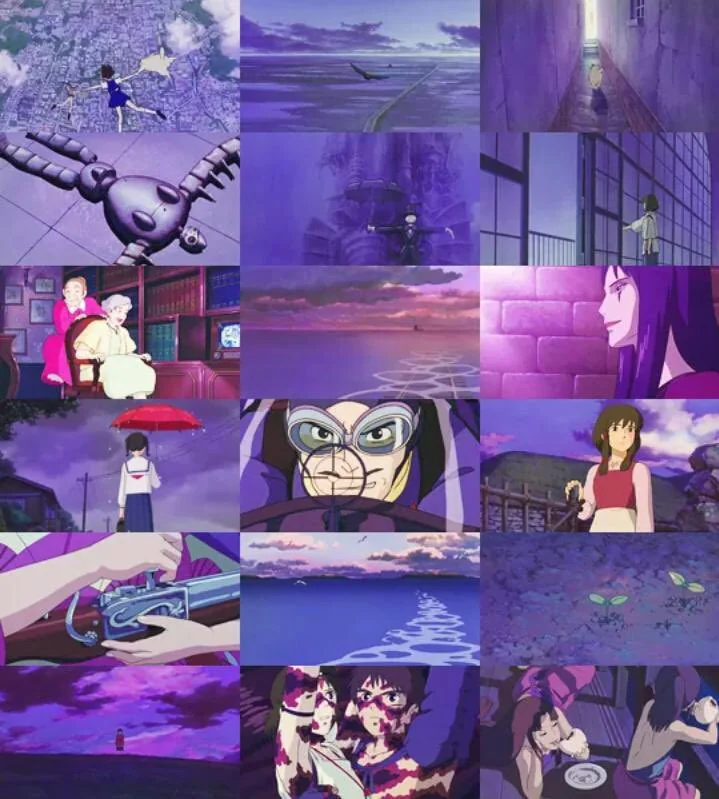
Michiyo Yasuda gave Ghibli its colour. This piece finally gives her the credit.
Interesting tutorial by Jonas Hietala on designing a personal Pebble watchface. I like the idea of using a watchface to display personal information, and this tutorial provides a good starting point for creating one.
Mechanical Pencil is a collection of illustrated tear-downs of everyday products by Bryan Macomber. The Zippo tear-down is particularly impressive.
Doug MacDowell writes about drawing data visualisations completely by hand.
“What are you working on these days?”
“Data visualizations.” I told him.
“Ah, you using algorithms, machine learning, cloud computing, things like that?”
“No.” I said. “I’m just trying to draw a line graph.”
My neighbor thought I was getting into some complex sh**. But what’s been more interesting to me lately than using […] is learning to draw data by hand. 50 Hours to Draw Some Lines is about spending more than a week on something that software can accomplish in 20 minutes - and a catalog of resources and methods acquired along the way.
Amanda Shendruk writes about the work that’s done after Burning Man, where 150 people line up, side by side and arms apart, and slow walk the entire playa looking for Moop (Matter Out of Place).
This forensic-style sweep takes weeks; everything they find is removed and logged. At the end, they’re left with a remarkable accounting of what 70,000 people left behind: The MOOP Map. And I’m obsessed.
The Moop Map is a pretty remarkable view of what is left behind:
Mario Zechner writes about the current usage of LLM coding agents in software development and how we just need to slow down our release cycles.
You have zero fucking idea what’s going on because you delegated all your agency to your agents. You let them run free, and they are merchants of complexity. They have seen many bad architectural decisions in their training data and throughout their RL training. You have told them to architect your application. Guess what the result is?
An immense amount of complexity, an amalgam of terrible cargo cult “industry best practices”, that you didn’t rein in before it was too late. But it’s worse than that.
Jacob Filipp writes about a moment in the 1980s when the Ontario Ministry of Education commissioned a computer designed specifically for students.
A time when public institutions believed they could build their own tools, and did.
1984 was an alternative reality where we could do things. Like build a computer in Ontario.
Ladybird (a new web browser), recently migrated part of their code base to a new programming language with the help of Claude Code and Codex (OpenAI’s code model). I thought this idea of human-directed LLM tasks is really great:
I used Claude Code and Codex for the translation. This was human-directed, not autonomous code generation. I decided what to port, in what order, and what the Rust code should look like. It was hundreds of small prompts, steering the agents where things needed to go. After the initial translation, I ran multiple passes of adversarial review, asking different models to analyze the code for mistakes and bad patterns.
Bruce MacEvoy, has an awesome website for water colour painters.